2026년 11월 10일 - Link Blog
가장 작고 효율적인 모델 소개: Muse Ember. Meta AI가 Claude Haiku/GPT Luna 카테고리에 진출하는 모델인 Muse Ember를 출시했습니다. 이 모델은 다음과 같이 설명됩니다:
[...] 복잡한 추론 실행과 에이전트들이 하루 종일 반복하는 작업(도구 호출, 코딩 서브태스크, 라우팅, 추출, 장문 문서 파싱)을 위해 설계된 가장 작고 효율적인 모델입니다.
더 짧은 프롬프트의 경우 GPT-6 Luna 및 Claude Haiku 5.5와 동일한 가격으로 책정되었습니다. 둘 다 입력 토큰당 백만 개 $0.10, 출력 토큰당 백만 개 $0.50입니다. 오늘 출시된 다른 대형 모델인 Claude Fable 5.2는 이보다 80배 높은 $8/$40에 책정되었습니다.
다만, 프롬프트가 길어질수록 가격 구조가 조금 덜 직관적입니다. Luna, Ember, Haiku 모두 최대 백만 개의 입력 토큰을 지원하지만, 가격이 상승하는 임계점(threshold)도 존재합니다. 그 임계점을 고려하면 Ember는 다른 두 모델 사이의 가격에 책정되었습니다:
| Model | Prompt size | Input ($/M) | Cached input | Output |
|---|
| GPT-6 Luna | ≤272k | $0.10 | $0.01 | $0.50 |
| ... | | | | |
하지만 요즘에는 토큰당 가격을 비교하는 것이 실제로 의미가 없습니다. 왜냐하면 추론(reasoning) 토큰의 경우, 같은 문제를 해결하기 위해 서로 다른 모델이 극적으로 다른 수의 토큰을 사용할 수 있기 때문입니다.
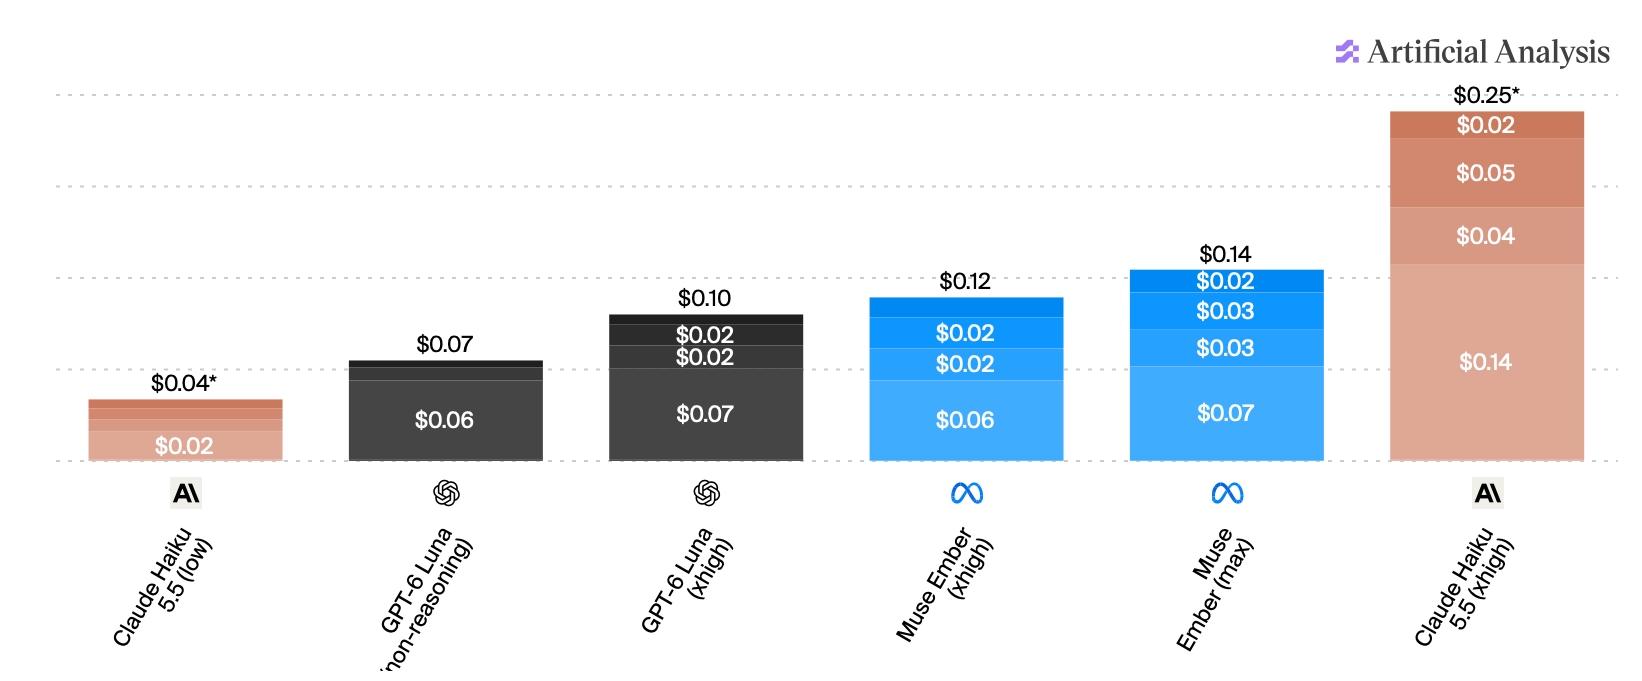
이를 위해 유용한 측정 지표 중 하나는 Artificial Analysis입니다.
Stacked bar chart from Artificial Analysis comparing a cost in dollars across six models, each bar split into four unlabeled stacked segments, sorted from lowest to highest total. Claude Haiku 5.5 (low): $0.04* total, bottom segment $0.02, three thin unlabeled segments above. GPT-6 Luna (non-reasoning): $0.07 total, bottom segment $0.06, thin unlabeled segments above. GPT-6 Luna (xhigh): $0.10 total, segments from bottom $0.07, $0.02, $0.02, plus a thin unlabeled top segment. Muse Ember (xhigh): $0.12 total, segments from bottom $0.06, $0.02, $0.02, plus a thin unlabeled top segment. Muse Ember (max): $0.14 total, segments from bottom $0.07, $0.03, $0.03, $0.02. Claude Haiku 5.5 (xhigh): $0.25* total, segments from bottom $0.14, $0.04, $0.05, $0.02. Anthropic bars are terracotta, OpenAI bars are dark gray, Meta bars are blue, each with the company logo beneath.
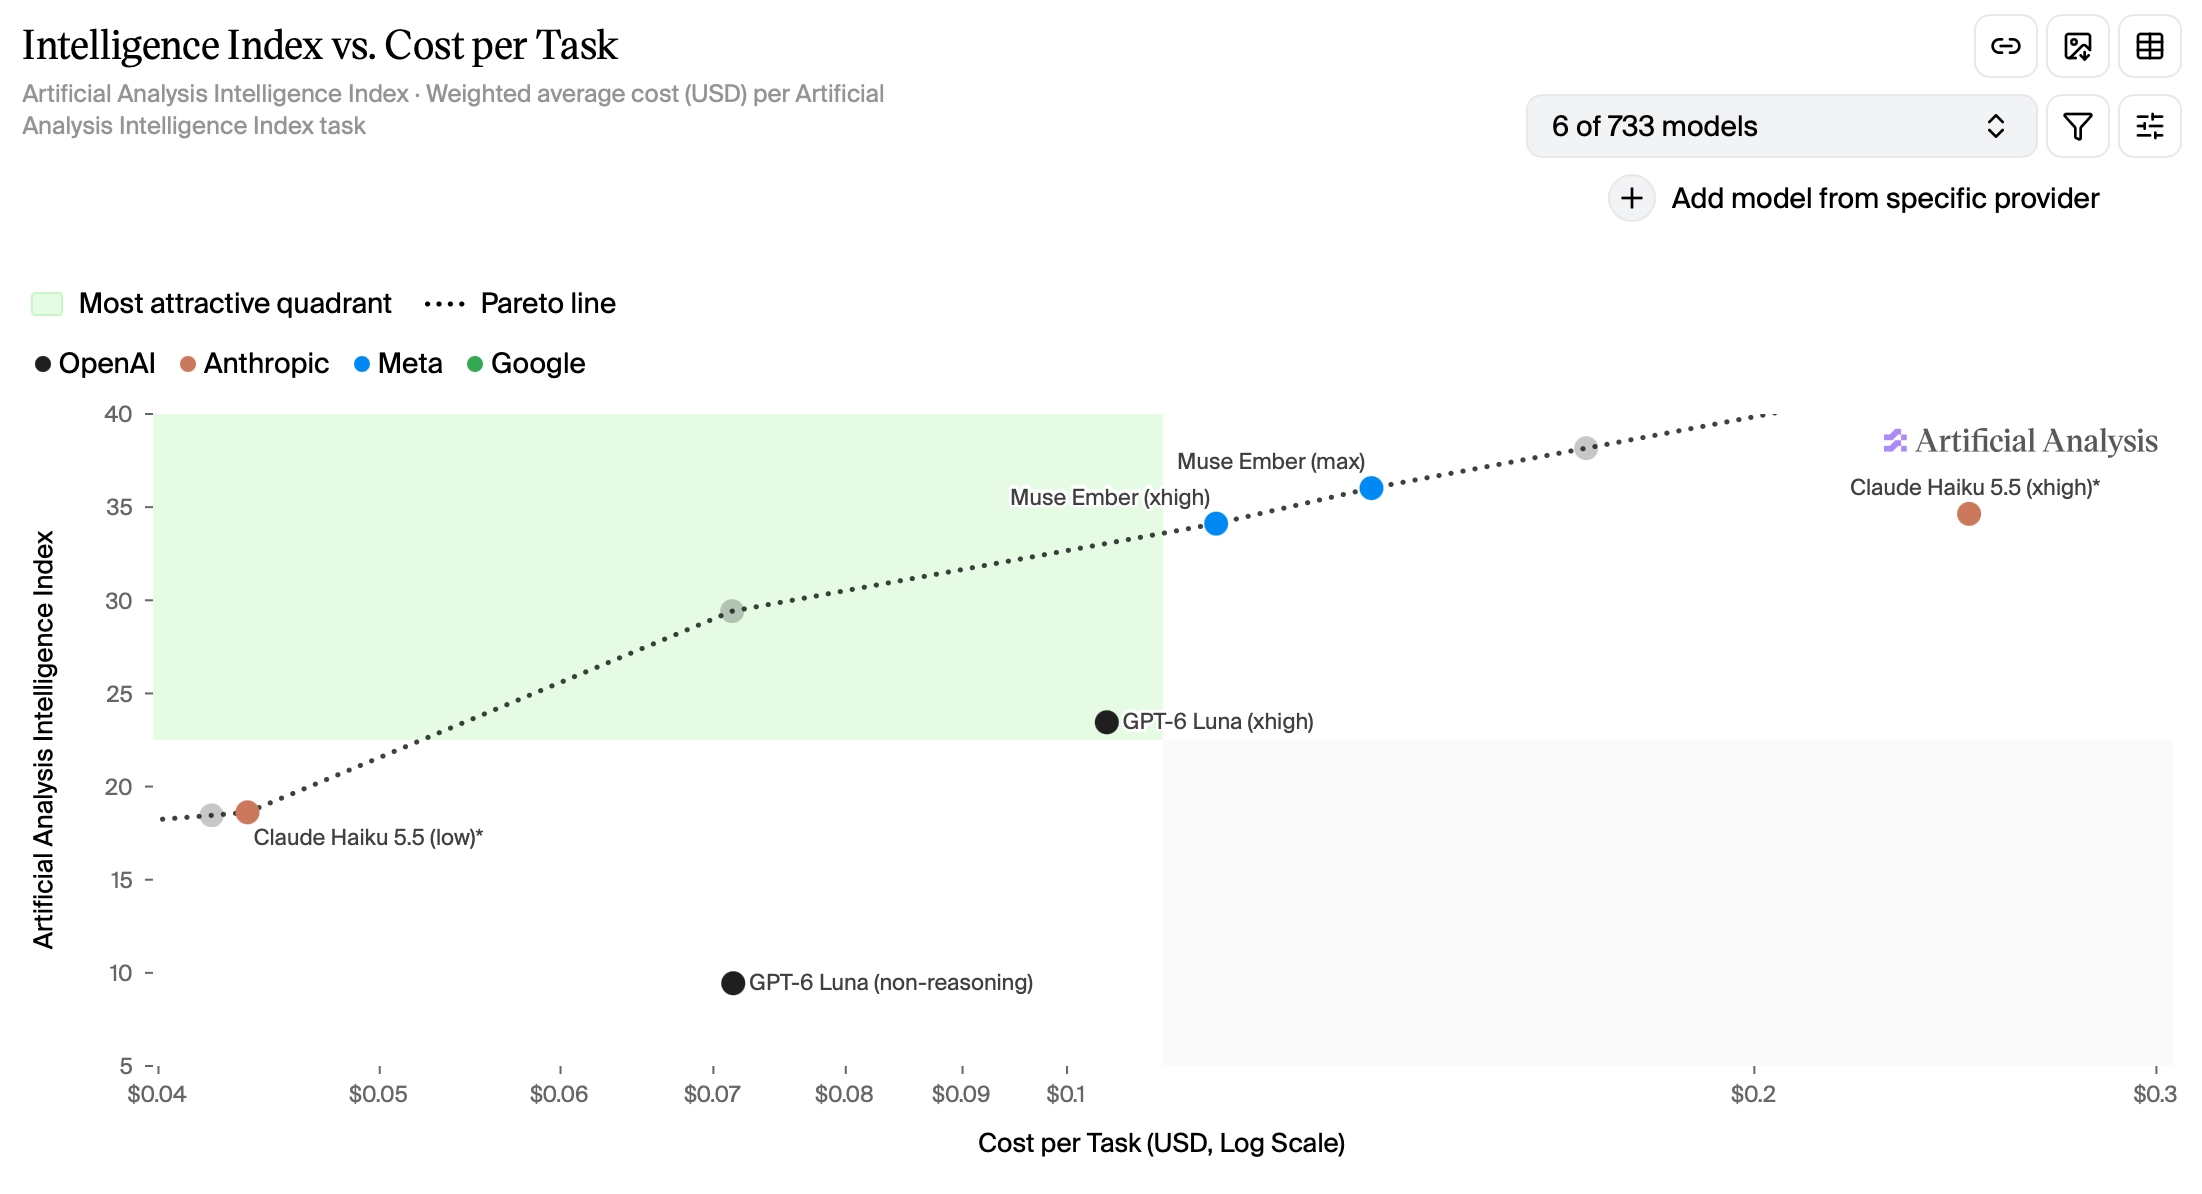
그리고 이보다 더 유용한 것은 Intelligence Index vs. Cost per Task 차트인데, 여기에는 세 가지 모델에 대한 다음 정보가 표시되어 있습니다:
Scatter plot from Artificial Analysis titled "Intelligence Index vs. Cost per Task", plotting Artificial Analysis Intelligence Index (y-axis, 5 to 40) against cost per task in USD on a log scale (x-axis, $0.04 to $0.3), with a green "most attractive quadrant" in the upper left and a dotted Pareto line. Claude Haiku 5.5 (low)* scores about 19 at roughly $0.044. GPT-6 Luna (non-reasoning) scores about 9.5 at roughly $0.07. GPT-6 Luna (xhigh) scores about 23.5 at roughly $0.10. Muse Ember (xhigh) scores about 34 at roughly $0.12 and Muse Ember (max) about 36 at roughly $0.14, both on the Pareto line. Claude Haiku 5.5 (xhigh)* scores about 34.5 at roughly $0.25, well to the right of the Pareto line. Three unlabeled gray dots also sit on the Pareto line.
Muse Ember 모델은 바로 그 Pareto 라인 위에 위치합니다. 이는 한 차원을 개선하려면 다른 차원을 포기해야 하는 선을 의미합니다. Meta는 발표에서 이를 언급했습니다:
이는 전체 Artificial Analysis 리더보드의 효율성 경계(efficiency frontier)에도 놓여 있습니다. 즉, 작업당 비용 대비 더 높은 점수를 받은 모델이 없습니다.
(녹색 영역 중앙에 있는 Pareto 라인의 회색 점은 GPT-6.1 Terra (low)입니다. 확실히 저는 Terra 계열에 더 주의를 기울여야겠습니다!)
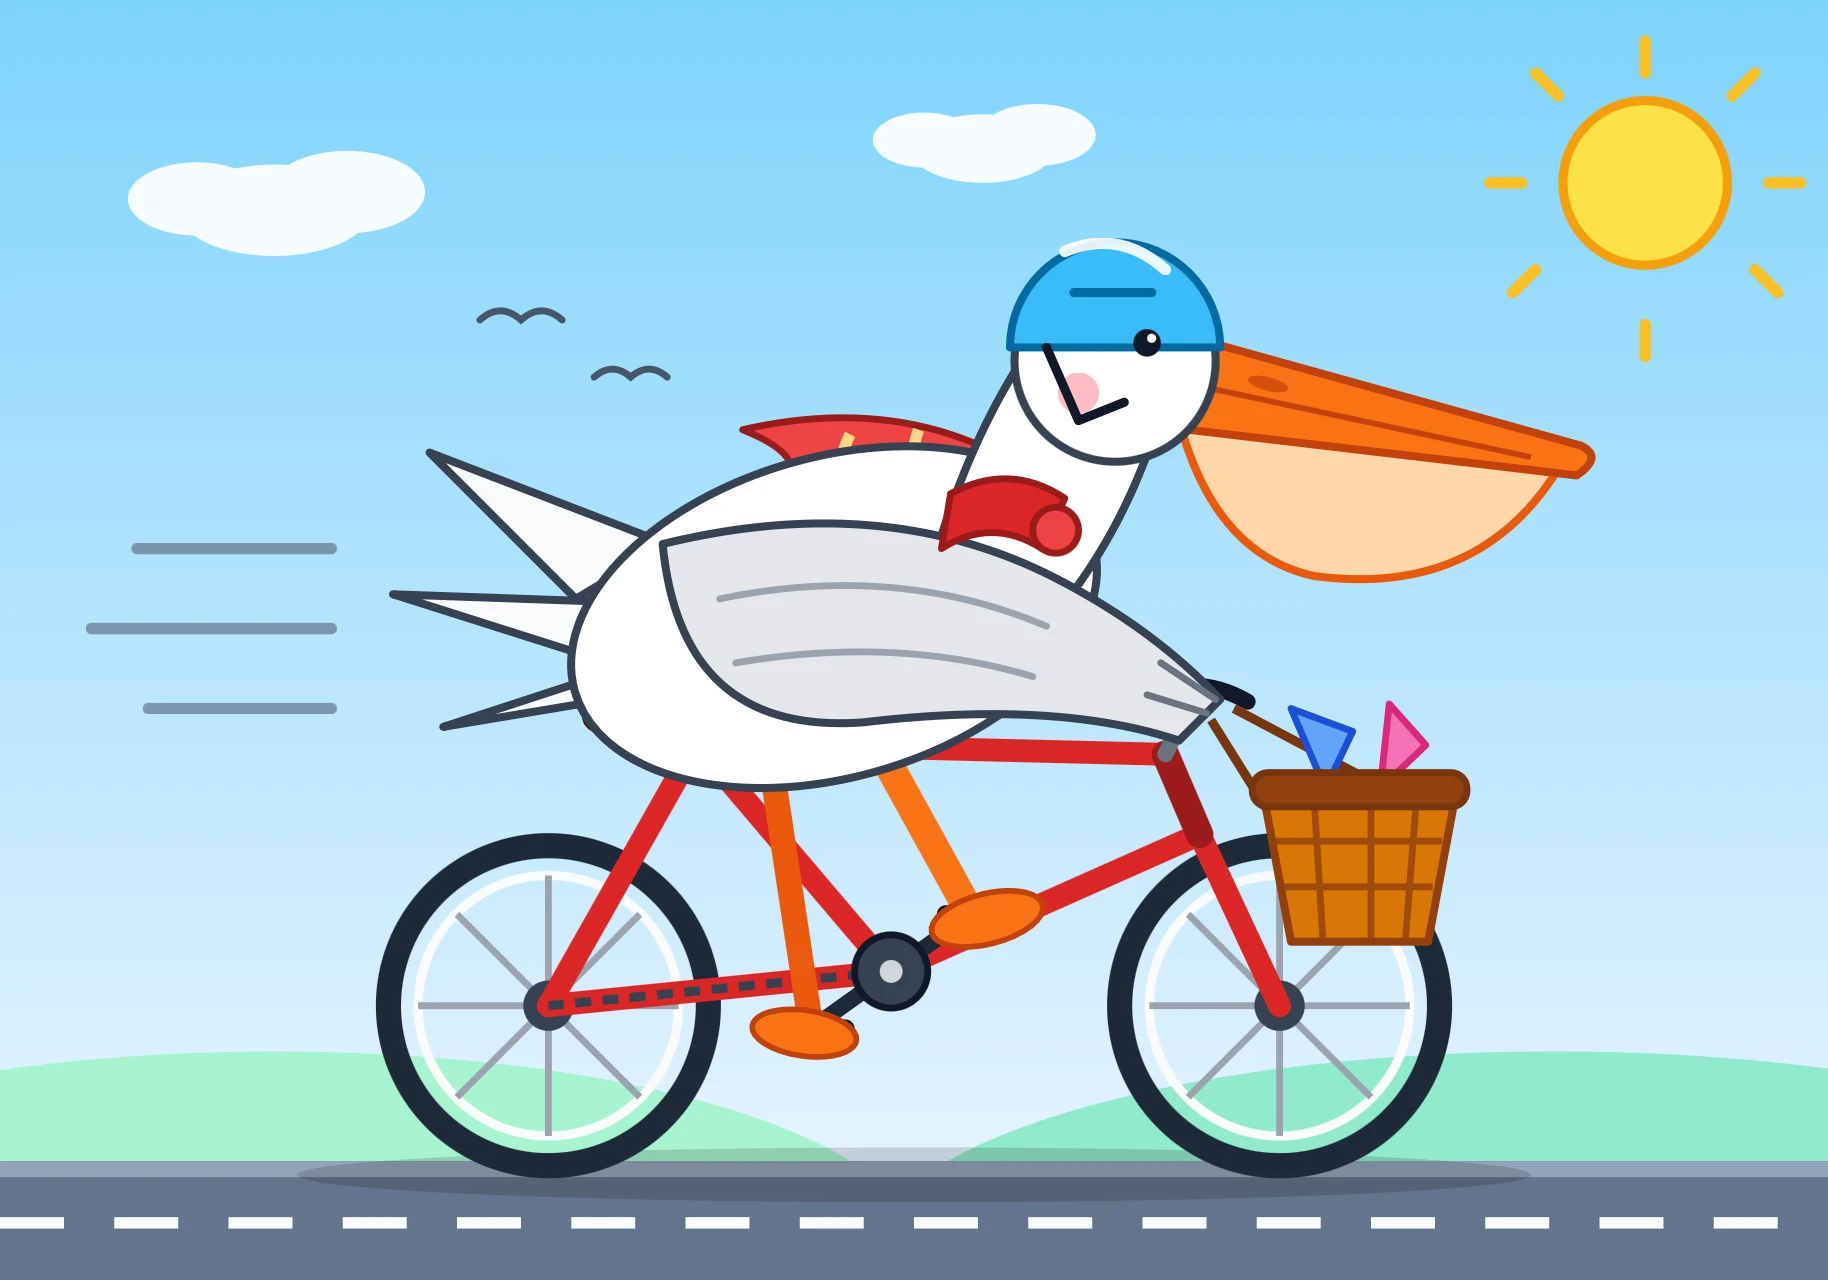
Muse Ember는 minimal, low, medium, high, xhigh, max의 여섯 가지 추론 수준(reasoning levels)을 가지고 있어, 자전거를 타는 백조 6마리를 렌더링했습니다. 'high' 추론 수준은 전체 SVG를 반환하는 데 실패했으며, 다른 SVG들은 추론 수준이 응답의 시각적 품질과 명확하게 일치하지 않아 놀라웠습니다.
여기 'max' 버전입니다만, 다른 것들도 살펴보는 가치가 있습니다:
Bicycle frame is OK, basket has fish, pelican has a weird blue hat on.
Ember 백조들은 Muse Ember보다 가격이 40배 비싼 Muse Wonder에서 얻은 것들과 비교할 만한 품질입니다.
최근 기사 (Recent articles)
- Claude를 사용하여 신비한 비프음의 근원지를 찾는 방법 - 2026년 11월 9일
<details><summary> 뒤에 지저분한 PR 설명을 숨기는 방법 - 2026년 11월 9일- 내 노트북에서 실행하는 Qwen 3.8 27B로 모델 가중치(model weights)도 해석할 수 있습니다 - 2026년 11월 3일
- 미국 인구조사국과 "초지능(Super Intelligence)" - 2026년 11월 2일